Latest
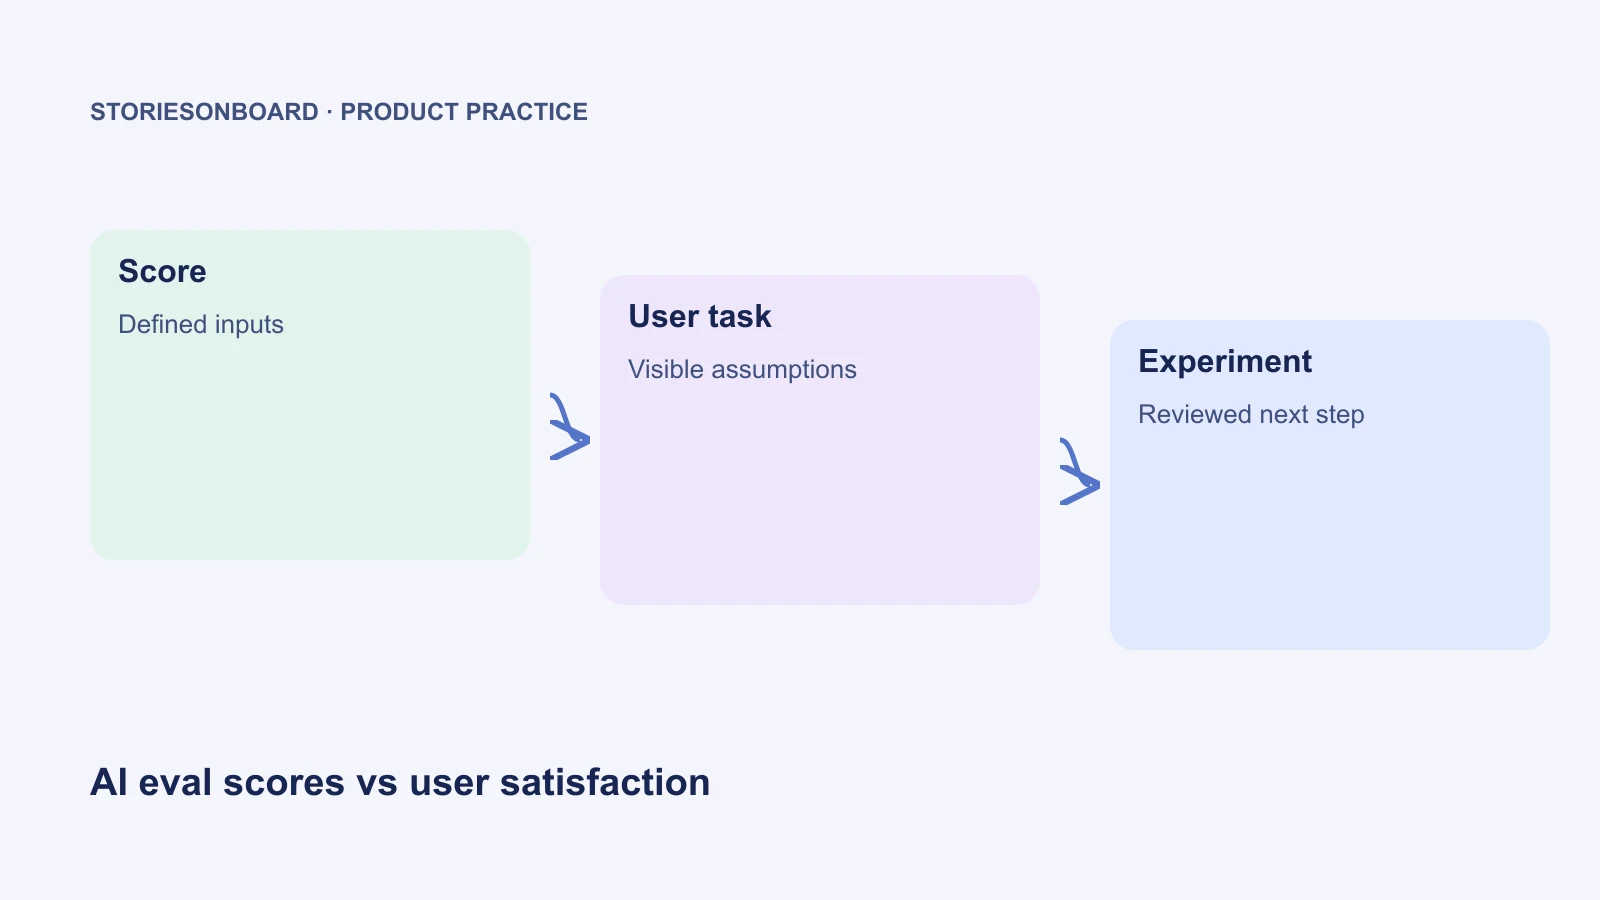
Your AI Passes Evaluations but Users Still Struggle. What Should You Change?
A green score can conceal an unusable workflow. Follow a prioritization example from a misleading rubric to task observation, diagnosis, and a controlled experiment.
A green score can conceal an unusable workflow. Follow a prioritization example from a misleading rubric to task observation, diagnosis, and a controlled experiment.
Every product team is using Claude. Very few are deploying it in a way that closes the real gap. This is the guide that shows you what the complete deployment …
MCP skills combine reusable AI workflows with live tool access. See how Claude and Codex handle skills, connectors, packaging, and product backlog work.
A green score can conceal an unusable workflow. Follow a prioritization example from a misleading rubric to task observation, diagnosis, and a controlled experiment.
Follow three complaints into repeatable tests. Preserve the failure mechanism, review expectations, and distinguish regression coverage from production incidence.
Choose the next experiment from the failure mechanism. Compare prompt changes, curated context, retrieval, and training against a common product task and evaluation set.
Create a quality baseline before changing an AI prompt or model. Work through eight cases, hand-scored answers, a copyable rubric, and explicit decision gates.
Turn verified product behavior into task-based documentation. Follow an invitation demo through an evidence packet, a drafting prompt, and a complete help-article sample.
Match the evaluation method to the failure you need to catch. Compare exact checks, claim support, expert judgment, and calibrated model grading through four worked cases.
Follow a fictional workspace invitation from a bounded brief to a working browser prototype. Use a requirement matrix, generation prompt, and click-through tests to review the result.
Give product workshops a shared vocabulary for screens, actions, decisions, and states. Build a small library, test it across two workshops, and connect the result to a story map.
Design a weekly feedback review that produces evidence-linked proposals. Keep scheduling, human approval, and backlog writes explicit, with checks for missing sources, stale records, and retries.
Reconcile the map with what users can actually do, keep new evidence distinct from delivery status, and assign ownership when research or a release changes the plan.
Take one user journey from a shared starting point to a proposed release slice. This 120-minute agenda includes quiet writing, facilitator prompts, a break, and follow-up decisions.
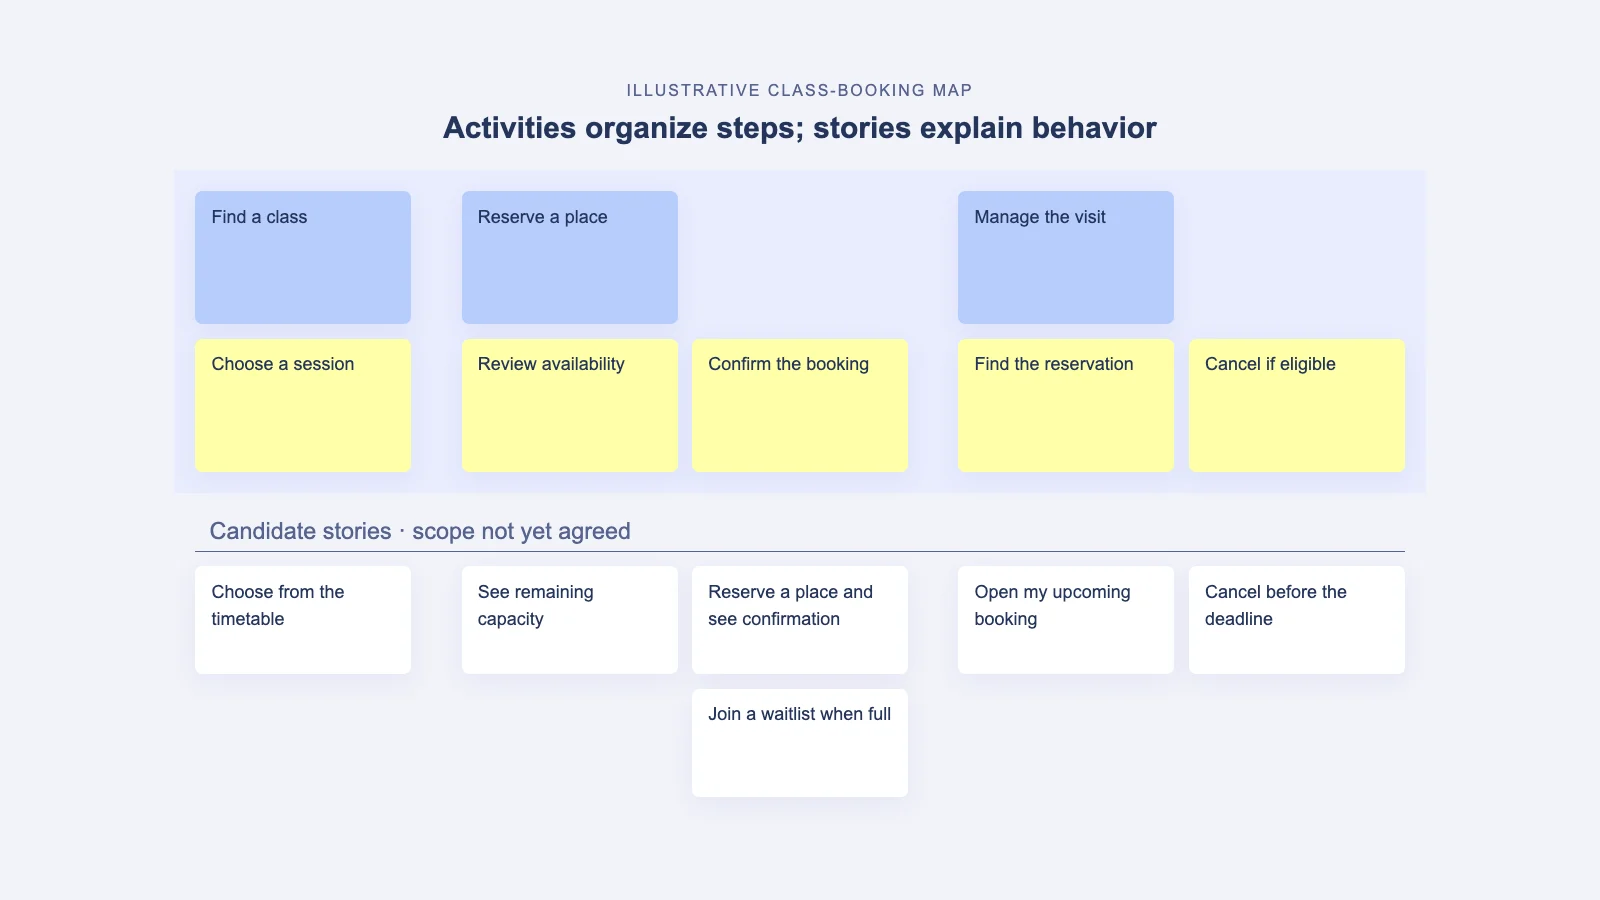
Place activities, steps, and stories at a useful level of detail. A worked class-booking example shows where ambiguous cards belong and how to repair a mixed-level map.